
Sentry, but for AI agents
LLM Evaluation Built for AI Agents
Latitude auto-generates evaluations from real production failures, not synthetic benchmarks. LLM-as-judge, RAG and multi-turn agent evals, calibrated to your product.
Trusted by thousands of engineers at companies like


The problem
Your agents fail silently. You find out from users.
Production AI is non-deterministic. Traditional testing catches the easy cases. The hard failures reach your customers first.
Invisible failures — no alerts, no clustering, just user complaints
Generic benchmarks — standard evals miss edge cases and tool-call errors
Built for LLMs, not agents — multi-turn, tool use, non-deterministic paths
The self-healing loop
From production failure to running eval in minutes
Latitude detects what breaks, generates the evaluation automatically, and keeps watching. No manual eval writing, no synthetic test suites.
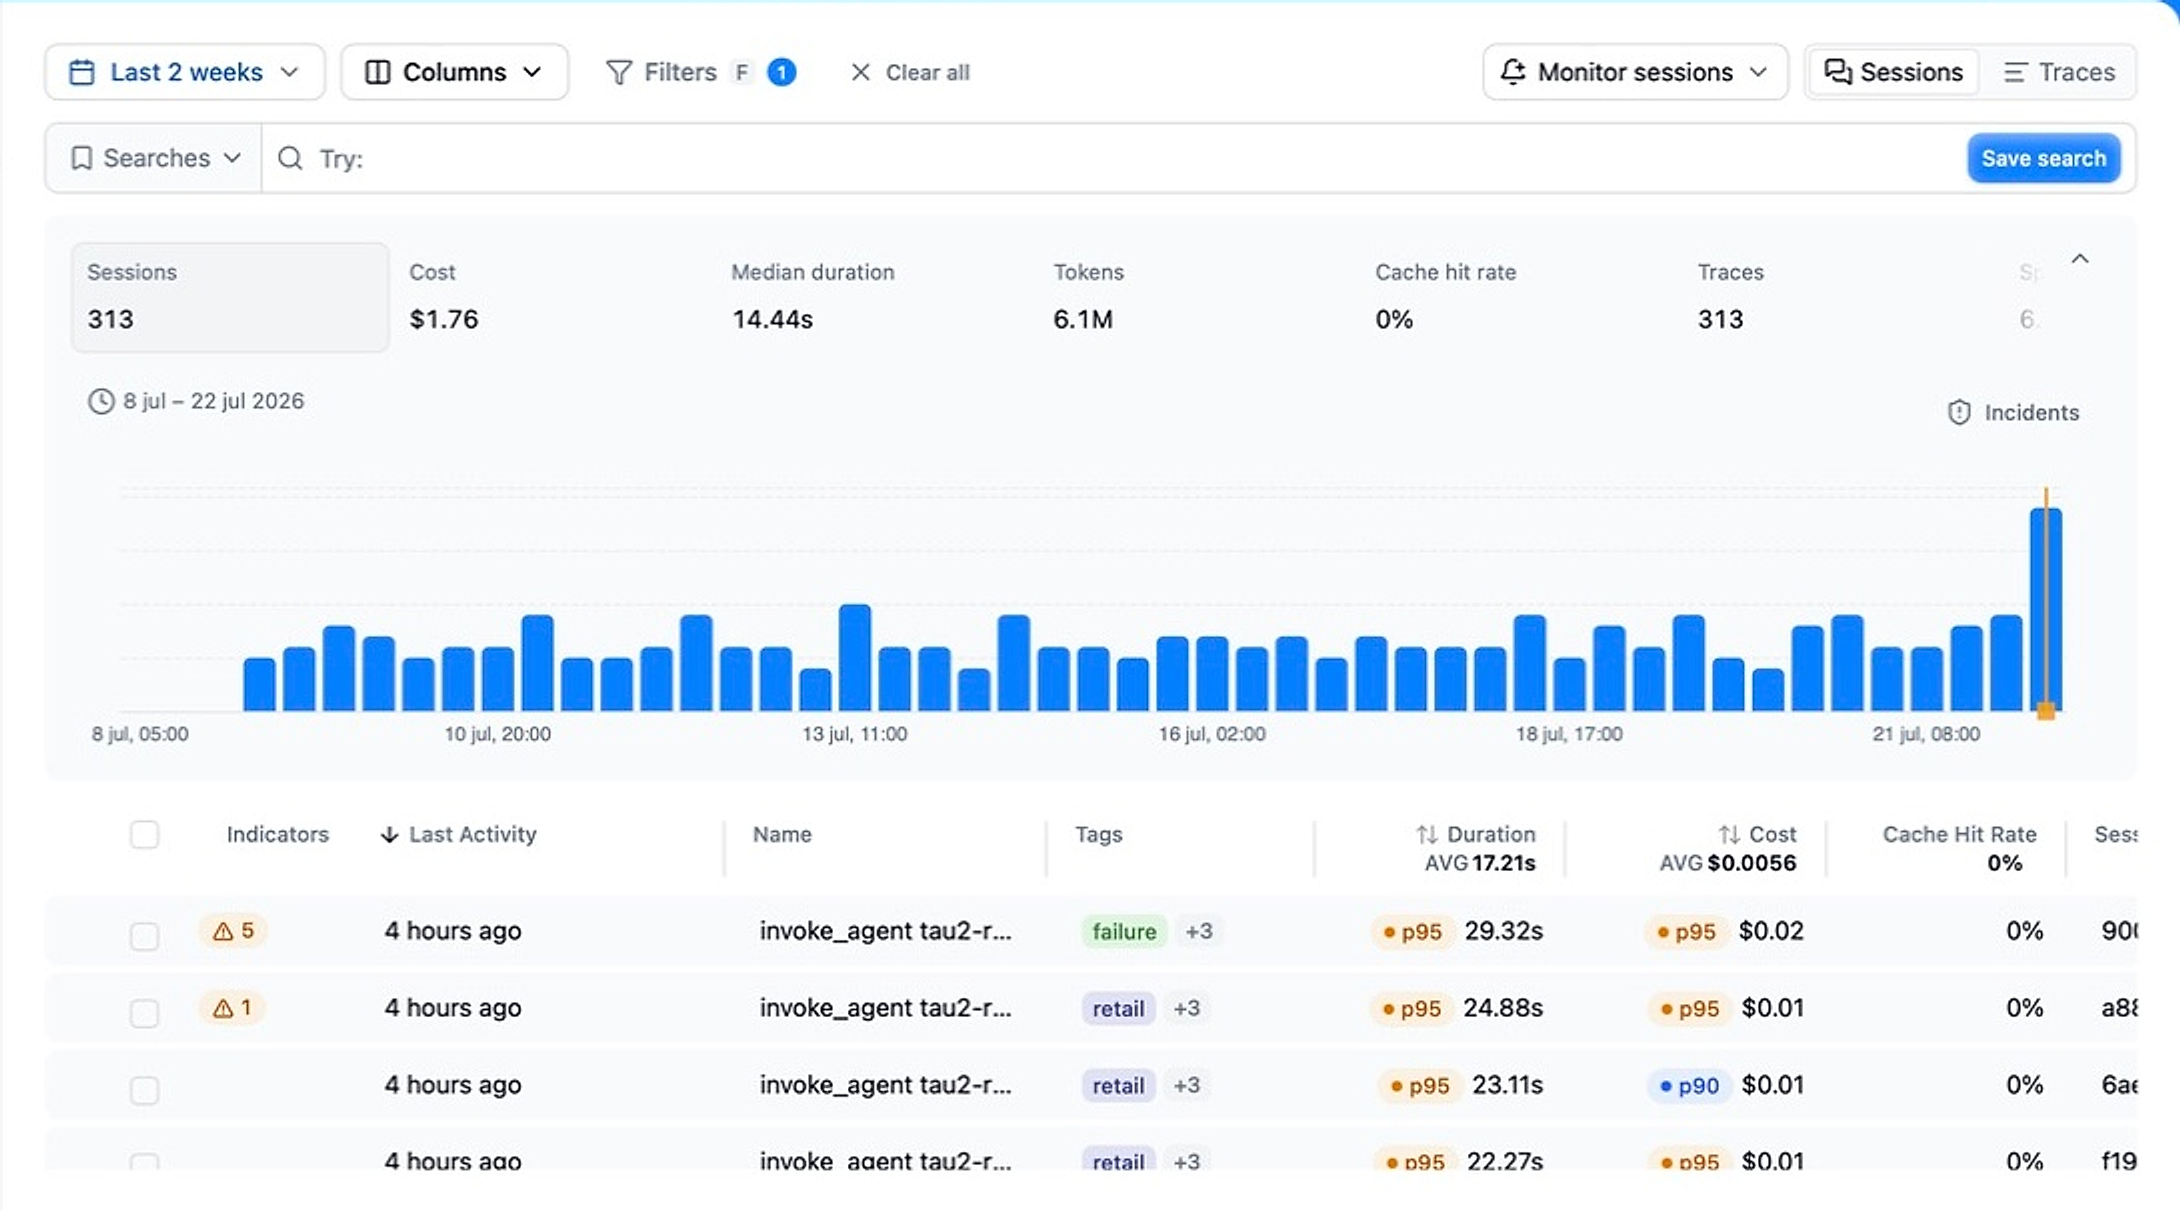
Detect failures
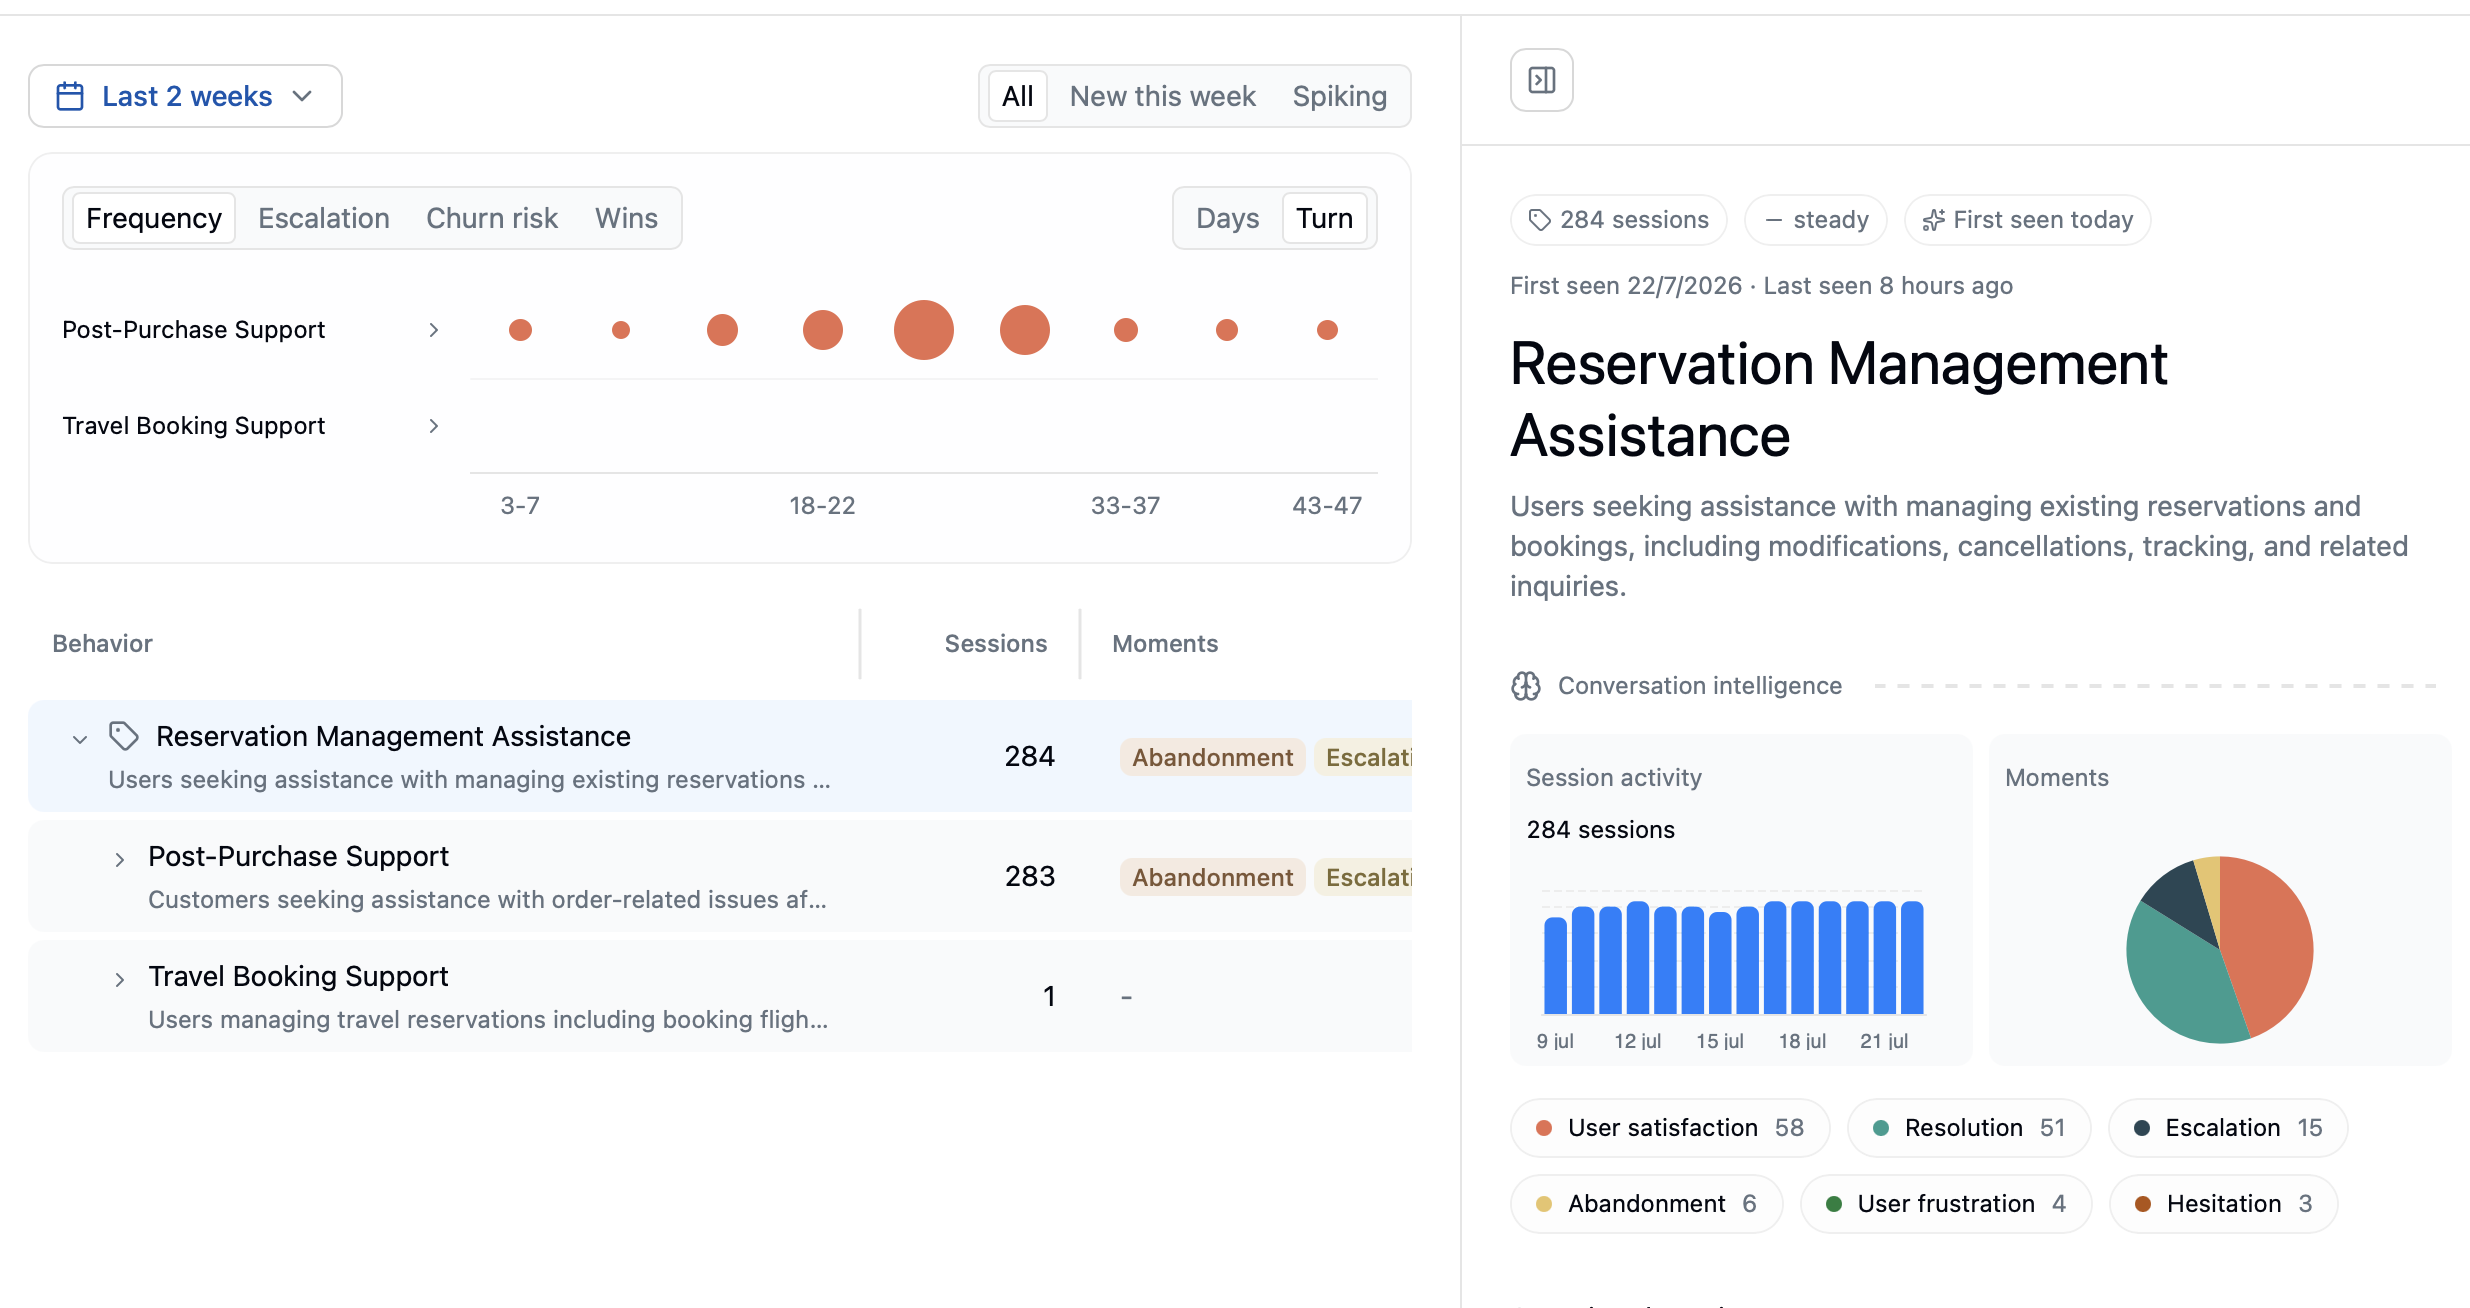
Trace every agent interaction in production. Latitude analyzes sessions, surfaces failures, and groups recurring patterns into prioritized Signals with lifecycle tracking.
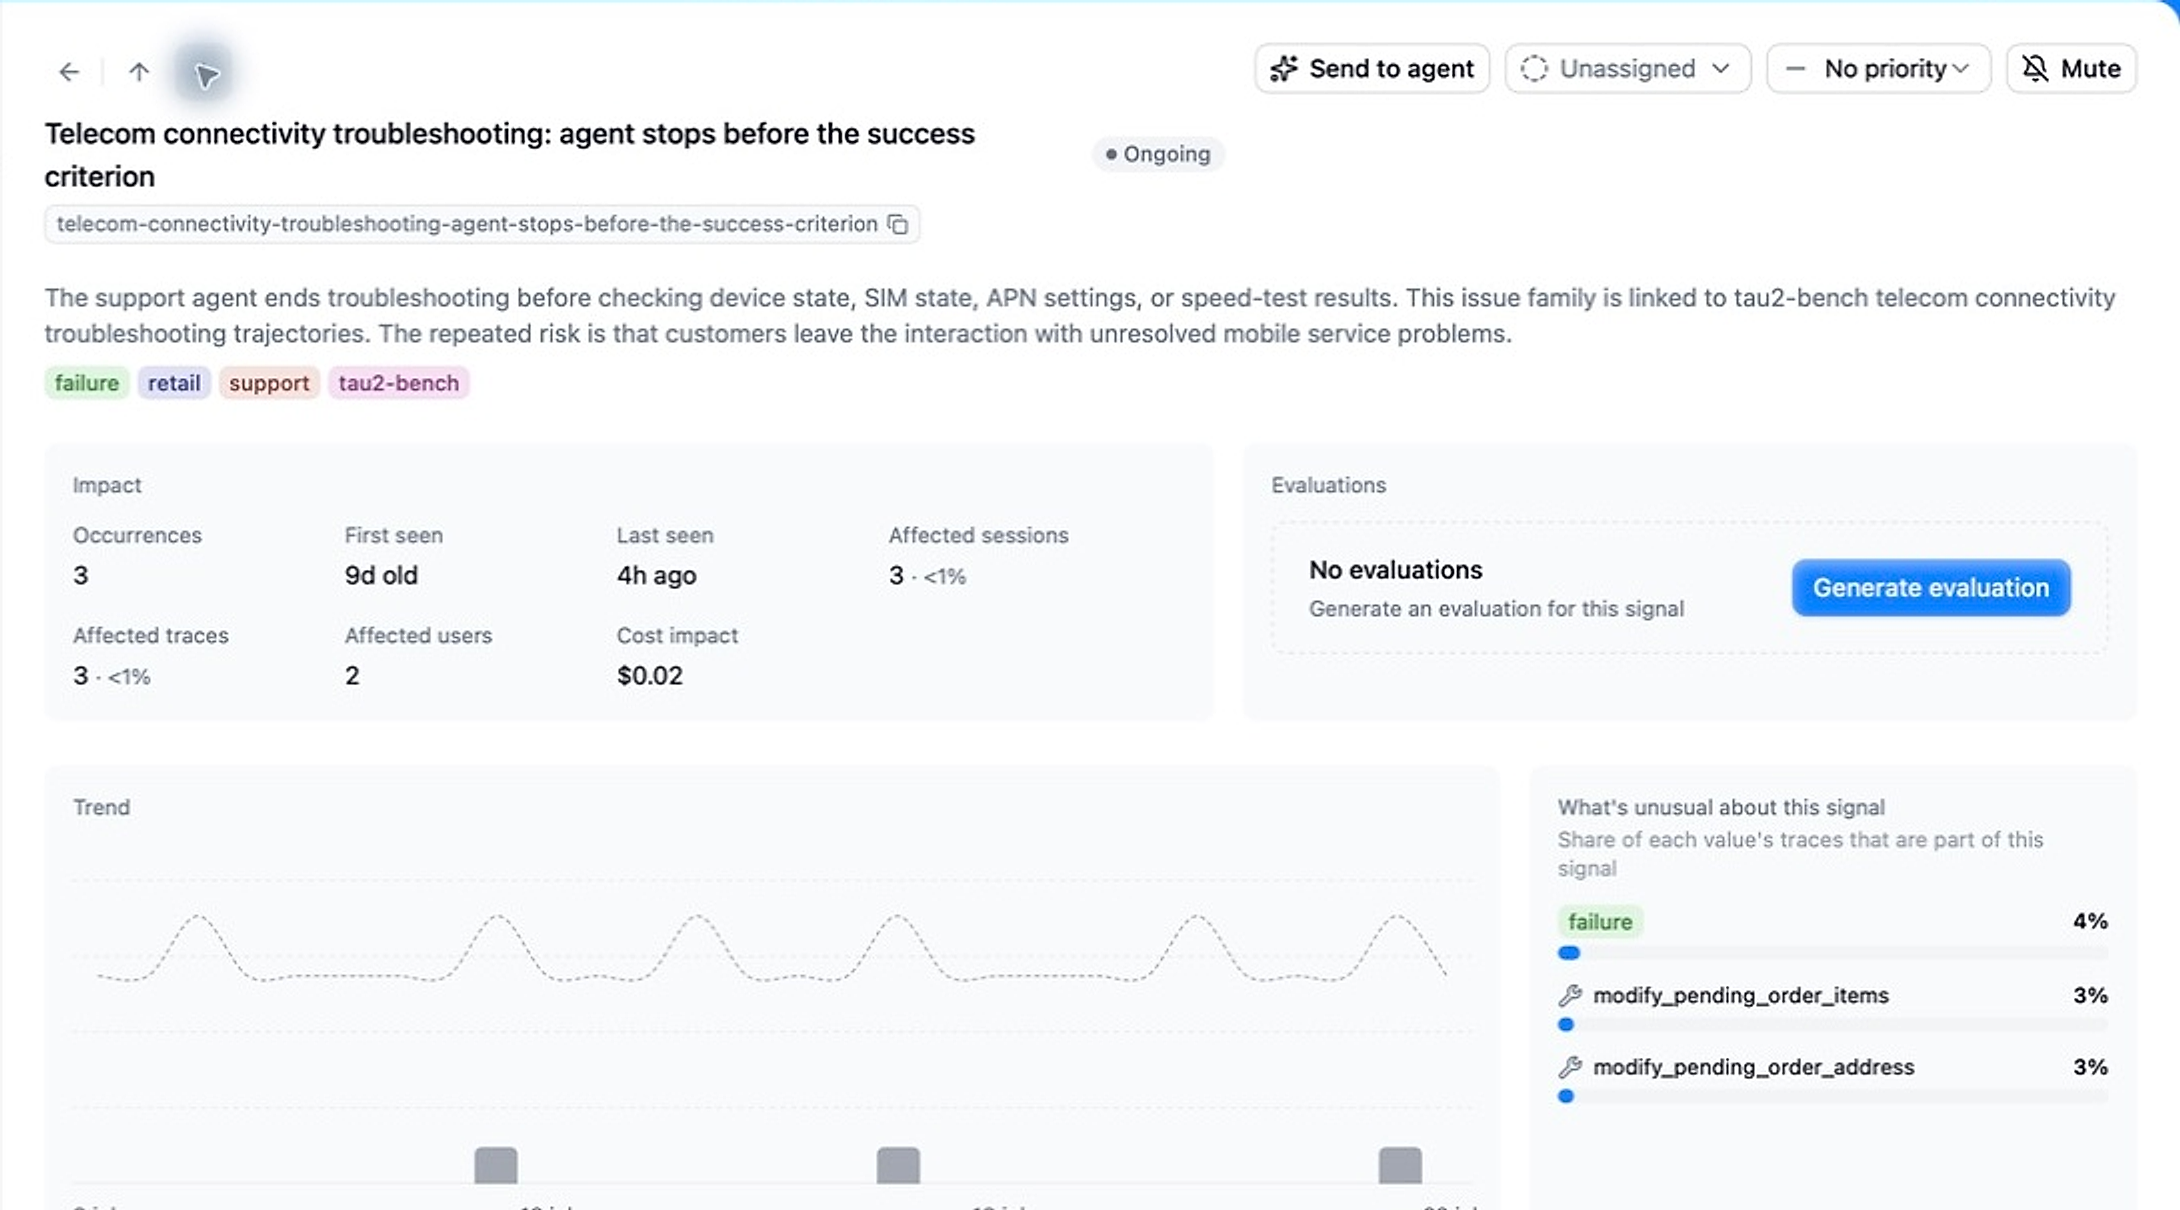
Auto-generate evals
Every Signal triggers an evaluation script automatically. No synthetic benchmarks. Evals built from real production failures, calibrated to your product with human annotations and MCC alignment.
Fix and verify
Dispatch your coding agent to implement the fix. Evaluations keep running on live traffic. If the failure recurs, the signal reopens. Continuous loop, zero manual eval writing.
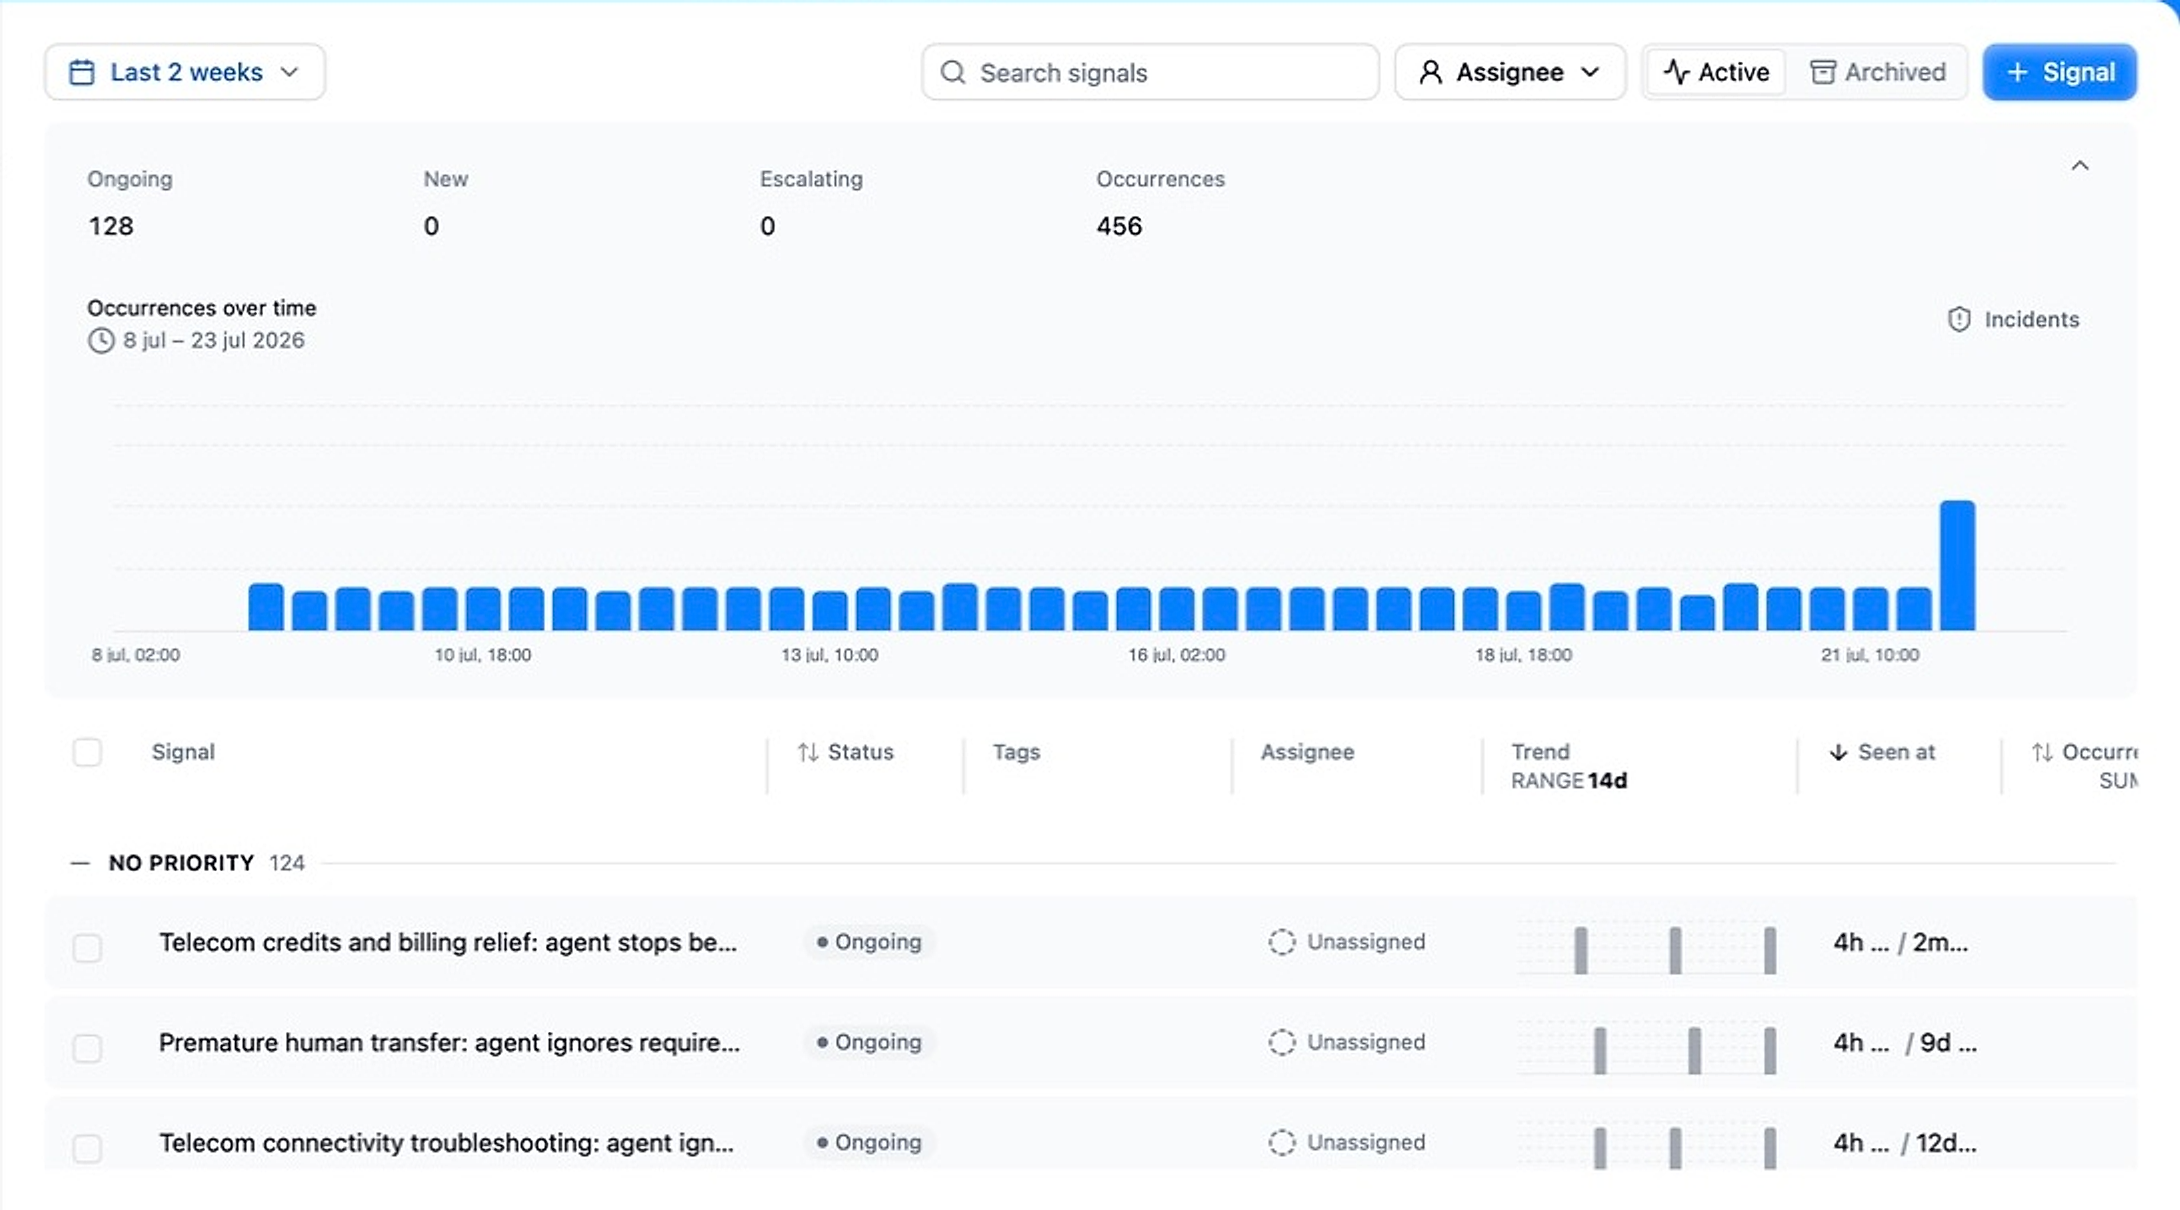
Continuous loop. Every fix makes the next detection smarter.
Evaluation types
Every eval your agents actually need
One platform for LLM-as-a-judge scoring, RAG evaluation, and multi-turn agent evals. All generated from production failures and calibrated to your product.
LLM-as-a-judge
LLM-as-a-judge, calibrated to your team
Score any agent output with an LLM judge that runs as a sandboxed script on live traffic. Human annotations set the ground truth, and MCC alignment measures how closely the judge agrees with your domain experts, so you see drift instead of trusting a black box.
- Judges run continuously on matching traces, not in one-off batches
- Annotations and built-in flaggers supply the ground truth
- MCC alignment score makes judge-vs-human disagreement visible
RAG evaluation
RAG and prompt evaluation from real traffic
Evaluate retrieval quality on the traces your RAG pipeline actually produced. Every issue Latitude opens generates its own eval script, so a retrieval failure you saw once becomes a check that runs on every request after it.
- Evals generated from the failing traces themselves, not a benchmark set
- Semantic search over trace conversations to find the failures worth scoring
- Same eval scripts reused in simulations before you ship
Agent evals
Multi-turn agent evaluation
Agents fail across turns, tool calls, and non-deterministic paths, not in a single request/response. Latitude scores whole sessions, so the eval sees the same context your user did.
- Session-level scoring across multi-turn conversations
- Tool-call and agent-state failures captured in the trace
- OTEL-compatible, so you instrument without replacing Datadog or Sentry
Multi-turn agent support
Built for multi-turn agents, not just LLM calls
Traditional tools were designed for simple request/response. Agents are different — multi-turn conversations, tool use, non-deterministic paths. Latitude was built for this from day one.
Traditional tools
-
Simple request/response
Single LLM calls only. No multi-turn support.
-
Static benchmarks
Generic test suites disconnected from production reality.
-
Manual eval writing
Engineers write every evaluation by hand. Maintenance nightmare.
-
Log dumps, not insights
Scattered traces. You spot patterns manually or not at all.
Latitude
-
Multi-turn agent workflows
Sessions, tool calls, complex state. Native support.
-
Evals from real failures
Auto-generated on issue creation. Not synthetic benchmarks.
-
Issue discovery + lifecycle
Some auto-detected, others found via semantic search. Named, prioritized, tracked (New → Escalating → Resolved).
-
Human-calibrated scoring
Annotations + MCC alignment keeps evals honest.
Agentic install
Let your coding agent install Latitude
Paste one prompt into Claude Code, Cursor, Windsurf, or Codex. Your agent instruments the app, connects the SDK, and you see traces in minutes.
Install the Latitude AI skill from github.com/latitude-dev/skills and use it to add tracing to this application. Integrations
Works with your stack. Setup in minutes.
OTEL-compatible SDK for TypeScript and Python. Pick your provider and framework below to see your exact setup code.
LLM Providers
 OpenAI
 Anthropic
 Google AI
 Azure OpenAI Vertex AI
 Bedrock
 Cohere
 Together AI
 Groq
 Mistral AI
 Ollama
Agent Frameworks
 LangChain
 LlamaIndex OpenAI Agents
 Vercel AI SDK
 Mastra
Trusted in production
Open source. Production tested. Community driven.
4,000+
GitHub stars
1,200+
Community members
 Slack
Self-host
Your infrastructure, full control
Commercial license available
8+
LLM providers
5+
Agent frameworks
OpenAI, Anthropic, LangChain, Vercel AI SDK, Mastra
MIT
Open source license
Full source on GitHub
Teams using Latitude in production
Pricing
Start free. Scale when you need to.
Unlimited seats on every plan. No per-user pricing.
Starter
- 20K credits/month
- Unlimited seats
- 30-day retention
- Full observability + evals
Pro
- 100K credits/month
- Unlimited seats
- 90-day retention
- $20 per 10K extra credits
Enterprise
- Custom volume
- Custom retention
- SAML SSO, on-prem
- SOC2, ISO 27001
Stop shipping AI blindly
See what's failing. Fix it systematically. Free plan, no credit card required.